Parny maps every service, dependency, and host. So when an incident hits, you get root cause, blast radius, and fix recommendations in under 30 seconds.
42%
intelligent correlation
eliminates noise
99.9%

See Parny AI in action
Trusted By
How It Works
From incident to insight.
Three steps. Thirty seconds.
Follow a checkout alert through dependency context, potential impact, and AI investigation in Parny.
01 Continuous Discovery
Parny auto-discovers every host, service, and pool in your stack and maps how they depend on each other. No manual config. This service context helps responders trace the relationships between an alert, its host, and dependent services.
02 Incident Detected
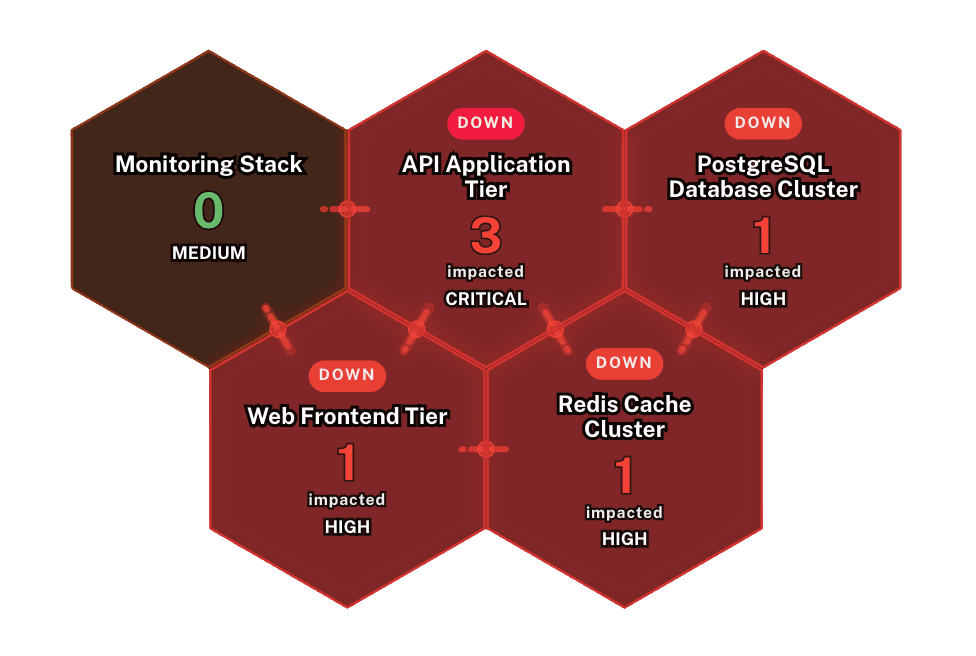
When an alert fires, Parny instantly maps the blast radius: which hosts, services, and customers are affected. Review correlated alerts alongside the service context to investigate whether several symptoms share a dependency.
03 AI Incident Summary
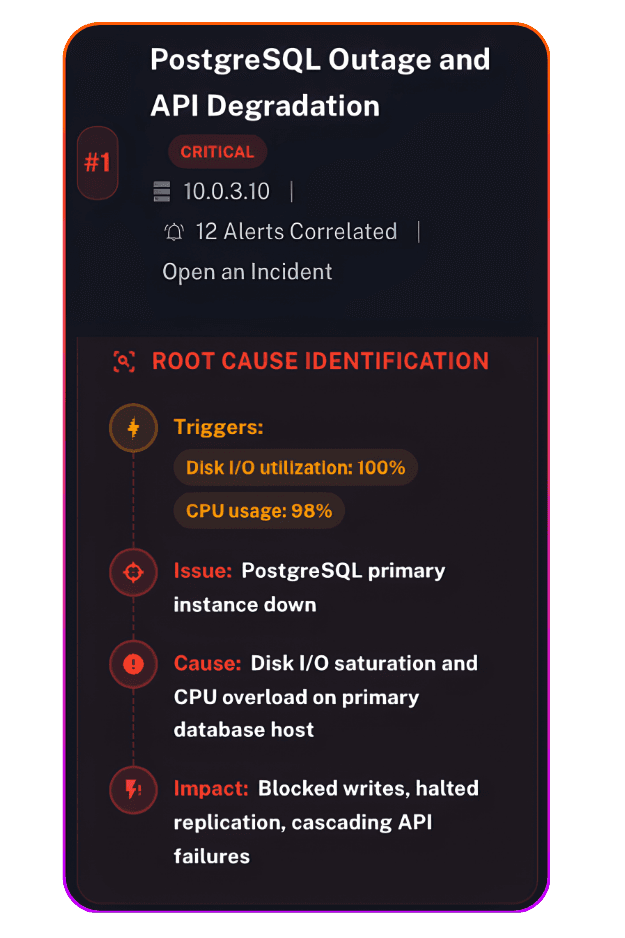
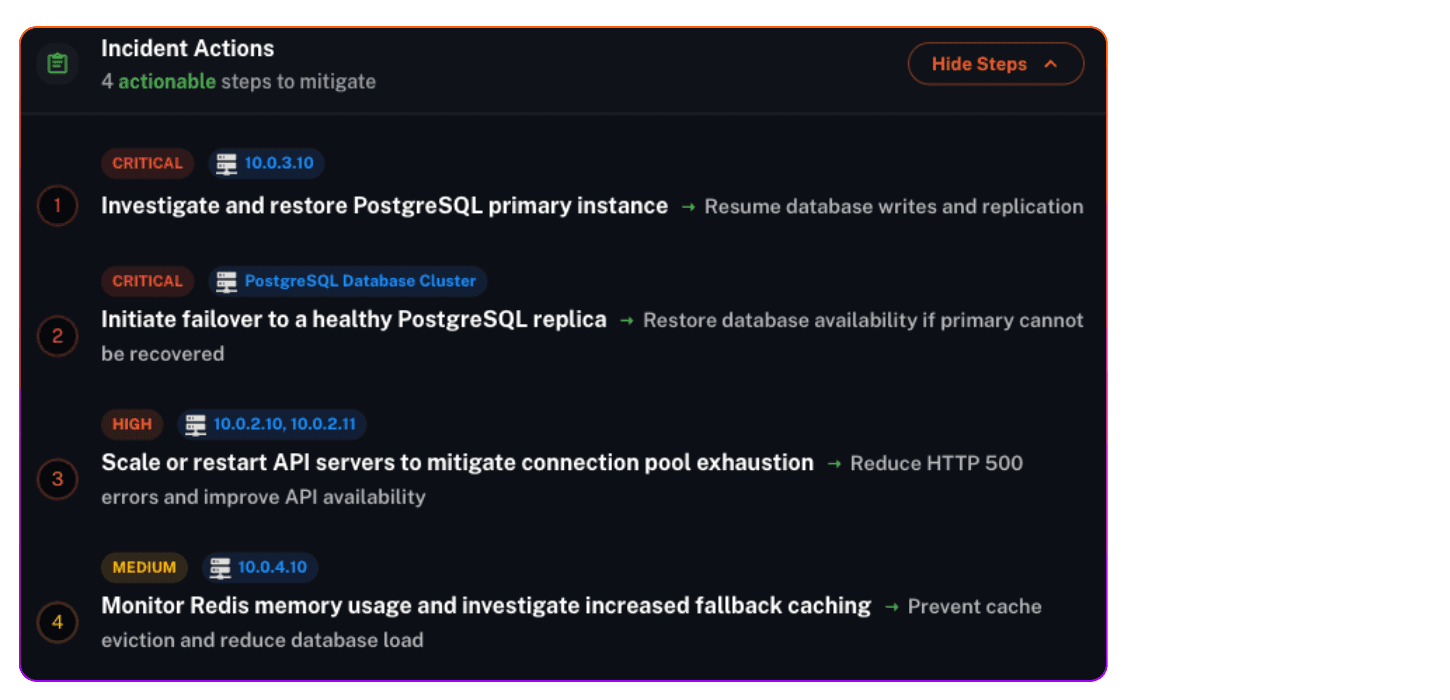
You get a structured report: severity, root cause, affected services, and prioritized actions to fix it delivered in seconds. Treat the root cause assessment as a hypothesis: validate it against current logs, metrics, and recent changes before taking action.
Core Capabilities
Impact Analysis
See which services, pools, and customers are affected — ranked by severity. No more guessing if it's P1 or P3.

Root Cause Assessment
Parny traces the dependency graph and resource saturation to find the actual source — not just the symptom.

Alert Insights & Predictions
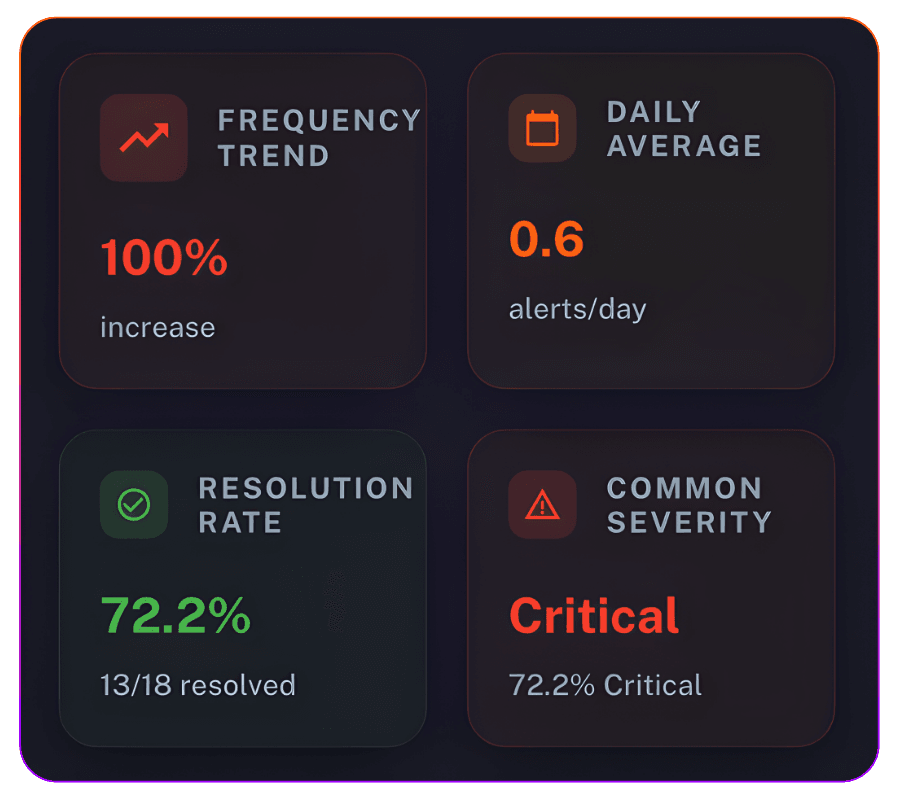
Spot recurring patterns before they become incidents. 'This alert fires every Tuesday at 3am' — now you know why.


Ongoing Incident Analysis
Live, updating view of active incidents: severity changes, new correlated alerts, expanding blast radius — all in real-time.


Recommended Actions
Prioritized, concrete steps: isolate this host, restart this service,
fix this monitoring gap. Not generic advice — specific to YOUR stack.

Health Assessment
One score per host, pool, and service. Green means healthy. When Parny says 'Needs Attention' — take it seriously.
For teams where downtime isn't an option.
SRE / DevOps Teams
Cut your MTTR in half. Get root cause and blast radius instantly instead of digging through 12 tabs during a 3am incident.
Platform Engineering Teams
Finally see how services actually depend on each other — not how they were supposed to. Parny maps your real infrastructure.
Cloud-native companies
Microservices, Kubernetes, multi-region — the more complex your stack, the more Parny shines. Built for distributed systems.
High-growth SaaS platforms
When every minute of downtime costs revenue, you can't afford to spend 20 minutes just understanding the incident.
FAQ
Got questions? We've got answers.
The investigation starts with correlated alerts and available service context. The AI summary brings together a root cause assessment, affected pools, endpoints and hosts, plus an action plan. Use it to choose the next checks, then validate the likely cause and impact against live evidence before making a change.
Illustrative workflow, based on the product screen above: PostgreSQL availability, CPU, disk I/O and replication-lag alerts appear alongside API errors. Review their shared dependencies, assess database resource saturation as a likely cause, and inspect the affected database, API and frontend services. Next, check current metrics, database logs and recent changes. A responder validates the findings and chooses the action. View the example product screen →

Review the recommendation first. Confirm that the cited signals are current, check the affected services and dependency context, and compare the proposed step with your runbook and change controls. The responder decides whether to act and checks recovery afterward. An AI-generated assessment should be verified before it is used to change production.
Parny connects to Prometheus, Grafana, Datadog, AWS CloudWatch, PagerDuty, OpsGenie, Zabbix, and 30+ other monitoring and alerting tools. New integrations are added every week. See full list →
Most teams are up and running in under 15 minutes. Parny auto-discovers your infrastructure — no manual topology mapping, no runbooks to write, no complex configuration.
Yes. All data is encrypted at rest and in transit. Parny never stores your raw logs or metrics — we only process metadata and alert signals. We're working toward SOC 2 compliance.
Most AIOps tools only correlate and group alerts. Parny auto-discovers your infrastructure, maps real dependencies, and gives you root cause + blast radius + recommended fix actions — all in under 30 seconds, with zero manual setup.
You'll transition to our standard pricing plan. No surprise charges — we'll notify you 7 days before your trial ends. You can cancel anytime. See pricing →
Yes! Parny AI works as a standalone API. You can integrate it into your existing incident workflow with a single API call, or use it alongside your current tools.