Most teams that start shopping for AIOps are not short of monitoring. They have Datadog or Prometheus. They have dashboards nobody opens. They have an alerting tool that wakes someone up at 03:40. What they are short of is the twenty, forty, ninety minutes between the page firing and somebody finally saying out loud, "it's the connection pool on the payments database."
That stretch is the expensive part of an incident, and it is the part nobody owns. Monitoring owns the signal. On-call owns the routing. The investigation in the middle gets done by whoever happens to be awake, in a Slack thread, by hand.
AIOps is the category that claims to own that middle. Whether any given product actually does is what your evaluation has to establish, and most evaluations never get there, because they test the demo instead of the gap.
What follows is the checklist we wish more buyers brought to the call. It is written to be used against any vendor, including us.
First, agree on what you are buying
AIOps has become a label rather than a definition. Three quite different products sell under it.
Alert consolidation. Ingests alerts from many sources, deduplicates and groups them, cuts the page count. Real value, narrow scope. It tells you which alerts belong together. It does not tell you why they fired.
Observability with AI features. An APM or log platform with anomaly detection attached. Powerful if you are already deeply instrumented on that vendor. Expensive and partially blind if you are not.
An investigation layer. Sits above the tools you already run, keeps its own model of how your services depend on each other, and answers "what broke, what does it affect, what do we do next" when an alert arrives.
These are not three versions of one thing. They solve different problems and they price differently. Before the first demo, write one sentence and make everyone in the room agree with it: the thing we cannot do today is ___. If the answer is "we get too many pages," you want the first kind. If it is "we can't tell what a payment failure is connected to," you want the third. Vendors will sell you either one under the same word, quite sincerely.
Map your stack before you compare anything
Draw three columns.
Signal: metrics, logs, traces, synthetic checks, cloud alarms.
Response: on-call schedules, escalation, paging, incident channels, postmortems.
Investigation: correlation, dependency context, root cause, impact.
Most teams fill the first two columns with product names and the third with a person's name. That third column is your requirement. The first two are constraints, because a platform that insists you replace them will die in procurement no matter how well it demos.
The ten criteria
For each: why it matters, how to test it, and what a weak answer sounds like.
1. Alert source coverage and integration depth
Why it matters. An investigation layer is only as good as what it can see. Coverage of your specific sources is binary. Either the integration exists or the evaluation stops here.
How to test it. Hand over your actual list, including the awkward entries. The legacy Nagios box. The bank's SNMP traps. The in-house script that curls an endpoint and posts to a webhook. Ask them to connect three of those during the trial, not to show you a wall of logos.
A weak answer sounds like: "We have 200+ integrations." Ask how many are bidirectional, and what happens to an alert whose payload doesn't match the expected schema.
2. Where the dependency map comes from
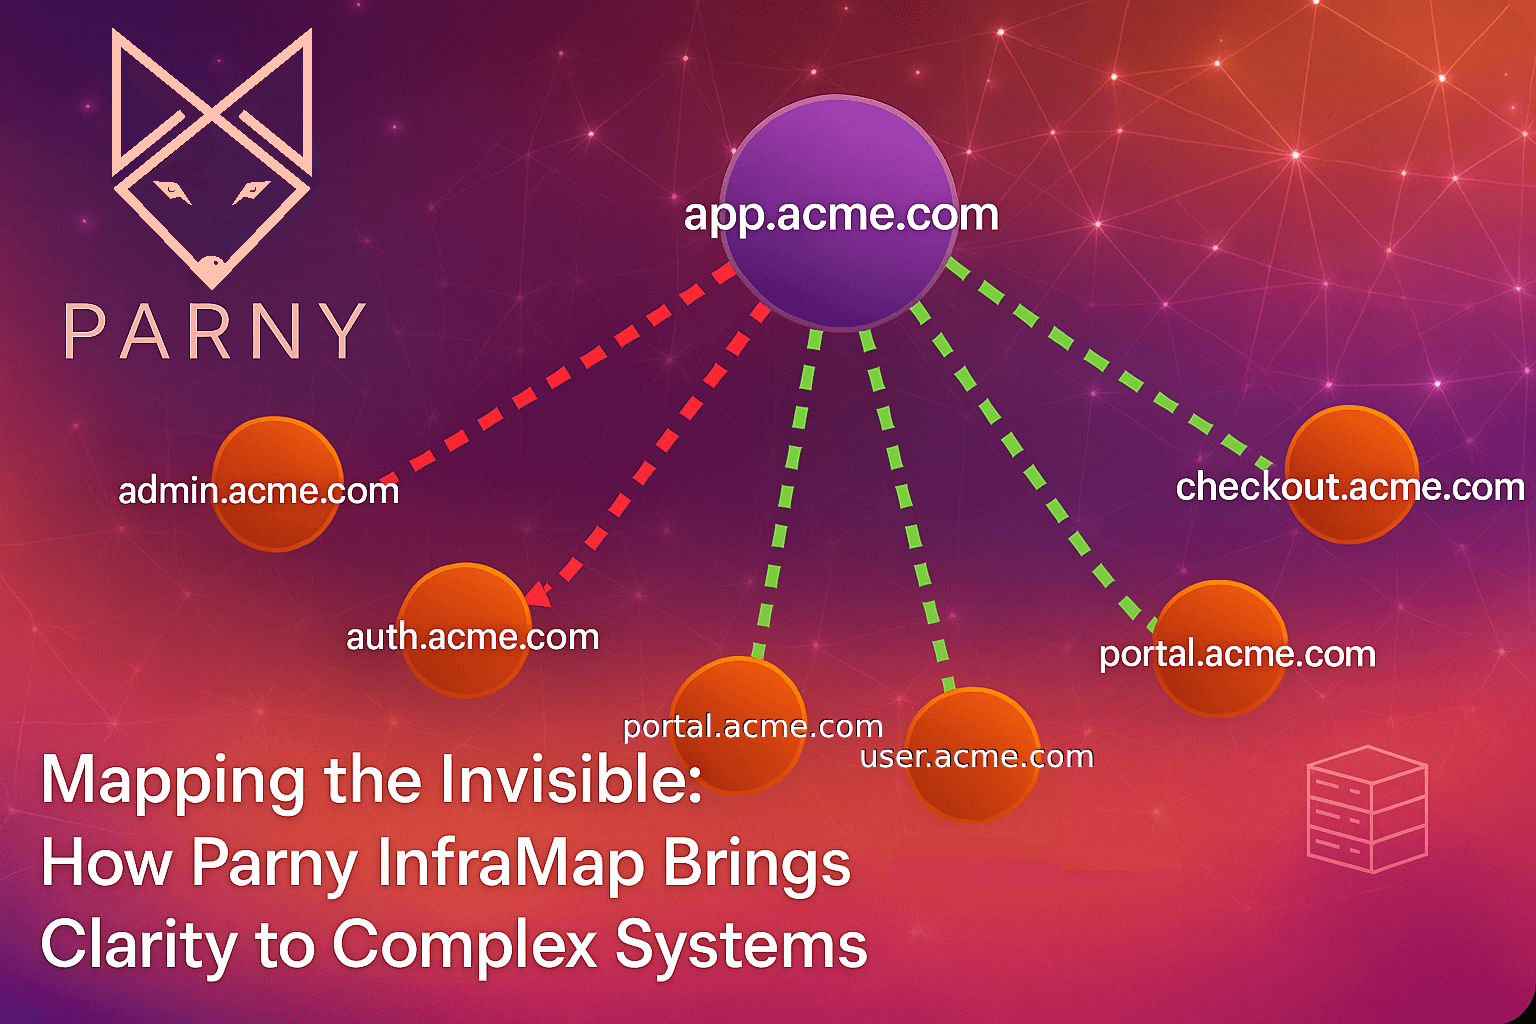
Why it matters. This is the question that actually separates these products, and it is the one buyers ask last. Correlation is only as good as the model of your system underneath it. If that model comes from a CMDB, it is exactly as current as the last time somebody updated a spreadsheet. If it comes from hand-written service definitions, it starts decaying the week after onboarding. If it is observed from the kernel itself, using eBPF, it reflects what your systems are actually doing rather than what someone wrote down.
There is a trade-off worth naming. Kernel-level agents have to be installed and they have to pass a security review. CMDB-based approaches avoid both. Decide which cost you would rather pay before you let a vendor decide for you.
How to test it. Ask how the topology is built, how often it refreshes, and what happens when a team ships a new service on a Friday afternoon without telling anyone. Then deploy into a non-production environment and look at the map after 24 hours, with nobody having drawn anything.
A weak answer sounds like: "We import your CMDB." You would be buying the accuracy of a document, not of your infrastructure.
3. Correlation and noise reduction, measured on your data
Why it matters. Every vendor in this category publishes a noise reduction percentage. Those numbers come from the vendor's own reference data, and they are not comparable across vendors because nobody defines noise the same way.
The underlying principle is not new. Google's SRE teams have argued for years that every page should be actionable, and that the distinction worth drawing is between symptom and cause, a point made at length in the SRE book's monitoring chapter. What is new is the claim that a model can draw that distinction for you. That claim is testable, and you should test it.
How to test it. Ignore the percentage entirely. Take one real alert storm from the last quarter, replay or reconstruct it, and count two things: how many separate pages your team received at the time, and how many incidents the platform would have opened. That ratio is your number. It is also the only one that survives a conversation with your CFO.
A weak answer sounds like: any percentage, from anyone, including us.
4. The shape of the root cause output
Why it matters. "AI-generated root cause" covers everything from a genuinely evidence-linked assessment to a confident paragraph that restates the alert in nicer words. The difference only becomes visible when you read ten of them in a row.
How to test it. Ask for ten real analyses, not the one that lives in the deck. For each, check three things. Does it name specific evidence. Can you click through to that evidence. Does it say what to do next, in priority order. Then ask what the output looks like when the platform doesn't know. A system that never says "insufficient signal" is telling you it will guess, and guessing at 04:00 is worse than silence.
A weak answer sounds like: a single beautiful screenshot that appears in every deck, always the same incident.
5. Impact analysis
Why it matters. The first question leadership asks is never "what broke." It is "who is affected." A platform that identifies a failing node but cannot tell you it sits underneath checkout has relocated the problem, not solved it.
How to test it. Pick a host. Ask which customer-facing services degrade if it dies, and ask how the platform knows that.
A weak answer sounds like: a list of infrastructure objects with no service-level meaning attached to any of them.
6. AI auditability
Why it matters. In regulated industries this criterion decides the deal, and it is the one most vendors are vaguest about. Your security review is going to ask what data leaves your environment, which model sees it, and how much the answer varies between runs. If you want a common vocabulary for that conversation, the NIST AI Risk Management Framework is the reference most enterprise security teams will already recognise.
How to test it. Ask which parts of the pipeline are deterministic and which involve a model, and get the boundary drawn explicitly. Ask for the formula behind any health or severity score. Ask which model provider is used and whether that is disclosed in writing under NDA. Then run the same incident twice and compare. You are not looking for byte-identical text, which no honest vendor can promise. You are looking for whether the conclusion holds.
A weak answer sounds like: "it learns from your environment over time," offered with no description of what is stored, where, or for how long.
7. Coexistence with the stack you already own
Why it matters. Rip-and-replace projects in observability have a poor completion record. A platform that only delivers value once it becomes the system of record will stall in month three, usually right after the budget is committed.
How to test it. Ask what breaks if you keep Datadog, Prometheus and PagerDuty exactly as they are. If the honest answer is "most of the value," you are looking at a replacement project wearing an AIOps label.
A weak answer sounds like: a migration plan you didn't ask for.
8. Data residency and what leaves your network
Why it matters. Deployment region, retention period, and what gets sent to a model provider are three separate questions. Vendors routinely answer one and let you assume the other two.
How to test it. Ask where the platform runs. Ask what is retained and for how long. Ask what payload is sent for AI analysis. Get all three in writing before the security review rather than during it.
A weak answer sounds like: a compliance badge offered in place of an answer. A certification is not a description of your data flow.
9. The pricing model, tested at your scale
Why it matters. Per-seat, per-host, per-gigabyte and per-event pricing behave very differently as you grow. The cheapest platform at 30 engineers can be the most expensive at 400 hosts, and you will find out in year two.
How to test it. Model three years at projected scale, not today's. Ask exactly what happens when the number of monitored assets doubles, and whether the unit you are billed on is something you control.
A weak answer sounds like: a price per user and a shrug about the asset side of the bill.
10. Time to first useful output
Why it matters. Platforms that need a six-week professional services engagement before producing anything tend to get abandoned during that engagement. This is also where the category is quietly competing now. The interesting question stopped being whether a product has AI and became how quickly it hands you something you can act on.
How to test it. Set a hard clock. Day zero is the first integration. Measure days until the first analysis a senior engineer agrees with. Then measure the number nobody advertises: how often the platform pointed the team in the wrong direction.
A weak answer sounds like: "once onboarding is complete."
Red flags worth naming out loud
A percentage improvement with no published methodology.
"Predicts incidents before they happen," with no account of what is being predicted, from which signal.
Autonomous remediation demonstrated on a scripted failure. Ask what happens when it acts wrongly at 04:00, and who is accountable.
A demo environment that is always the same three services.
Root cause output that cannot be traced back to a specific piece of evidence.
Reluctance to name the model provider under NDA.
A reference customer who cannot be reached without the vendor in the room.
A scoring sheet you can actually use
Score each criterion 1 to 5, weight it against your own situation, sum. The weights below are a starting point for a team that already has monitoring and on-call in place.
# | Criterion | Suggested weight |
|---|---|---|
1 | Alert source coverage | 10% |
2 | Source of the dependency map | 15% |
3 | Correlation measured on your data | 15% |
4 | Shape of root cause output | 15% |
5 | Impact analysis | 10% |
6 | AI auditability | 10% |
7 | Coexistence with existing stack | 10% |
8 | Data residency and data flow | 5% |
9 | Pricing model at your scale | 5% |
10 | Time to first useful output | 5% |
If criteria 2, 3 and 4 together do not carry the largest share of your weighting, you are evaluating an alerting tool rather than an AIOps platform. That may be the right purchase. Just know which one you are making.
A 30-day evaluation plan
Days 1 to 5. Connect two or three real alert sources. Deploy agents or collectors across a representative slice of infrastructure, including at least one database host and one service with a non-obvious dependency.
Days 6 to 10. Leave it alone and let the topology build. Then open the map and check it against what your senior engineers believe to be true. Every wrong edge is a data point, and so is every edge they didn't know about.
Days 11 to 20. Run in parallel with your current process. For each real incident, record what your team concluded, what the platform concluded, and how long each took.
Days 21 to 25. Replay a historical alert storm. Count pages against incidents.
Days 26 to 30. Score. Write down the two things that would have to be true for this to fail in production, and ask the vendor to address both in writing.
Fix your thresholds before day one. Criteria written after you have seen the results are not criteria, they are rationalisations.
Where Parny fits, and where it doesn't
We build an AIOps platform, so it would be dishonest to publish this and pretend we have no position in it. Here it is plainly.
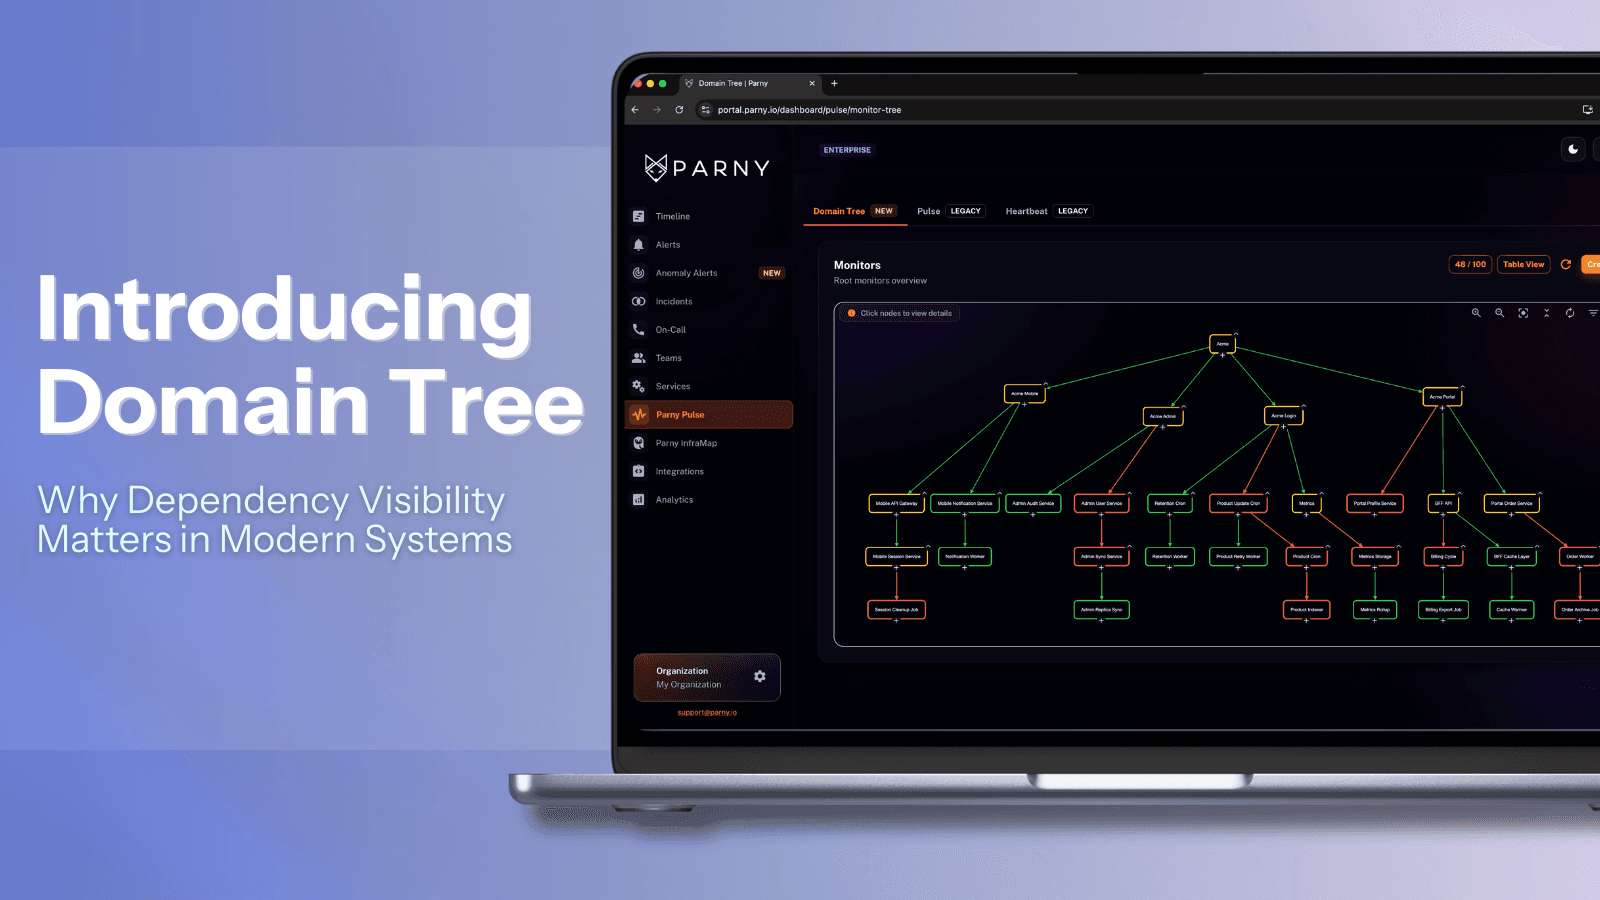
Parny is the third kind of product described at the top. An intelligence layer that runs above the monitoring and alerting tools you already own. It ingests alerts from your existing sources through our integrations, and separately builds its own view of your infrastructure using eBPF-based dependency mapping from agents on your hosts, discovering services and the traffic between them rather than reading them out of a CMDB. Service Discovery and Infrastructure Visibility keep that view current. When an incident opens, Parny AI produces a root cause assessment, the affected services, and prioritised next actions. Impact Analysis and Health Score answer the "who is affected" question in service terms rather than host terms. On-call scheduling, escalation and uptime monitoring are in the platform, so teams replacing an end-of-life alerting tool can consolidate, and our pricing reflects that consolidation rather than charging for each piece separately. That is the scope, not the headline.
On criterion 6 we will go further than most vendors will. The clustering stage is deterministic: same inputs, same groups, every time, with no model involved. The Health Score is computed by a published formula, also with no model in the periodic run. Where a model is involved we run controls to reduce variance between runs rather than claiming to eliminate it, because nobody running a language model in production can honestly promise byte-identical answers. We name the model provider in writing during security review, and we will tell you which part of any analysis came from the deterministic side and which did not.
Where we are not the right answer:
If you need a mature ITSM workflow engine with change management and CAB approvals, buy ITSM. We are not that, and we are not trying to become it.
If your problem is code-level profiling and distributed tracing, buy an APM. We sit above one. We do not replace it.
If you run a dozen services and one team, the investigation gap is small enough that a good on-call tool and a competent engineer will beat any platform on this list.
If your estate is entirely serverless with no hosts to instrument, our dependency mapping loses most of its advantage.
We would rather you scored ten vendors honestly and chose somebody else than win a deal that unwinds in month four.
The one question
If you only get fifteen minutes with a vendor, ask this. Show me a root cause analysis from a real incident last week, and show me the evidence it was built from.
Everything else in this guide is downstream of the answer.
Evaluating options before April 2027? Atlassian announced the end of Opsgenie in March 2025. New sales closed on 4 June 2025, and support ends on 5 April 2027. After that date access to Opsgenie goes away, and only what you have already migrated remains available in Jira Service Management. A lot of teams are running this exercise right now for that reason.
If you want to run the 30-day plan against us, Parny’s full AI bundle is available as a 14-day free trial. That gives you enough time to connect your existing stack, build infrastructure context, and evaluate Parny against real incidents alongside your current process. After the trial, you can downgrade to Freemium and continue using Parny while you complete your evaluation. Start a 14-day free trial, or compare Parny against the platform you're considering.