Almost every incident management and observability vendor now offers AI root cause analysis. The label covers very different products: some summarize alerts, some query telemetry step by step, some reason over a model of how your services depend on each other. All of them produce a confident paragraph that names a cause.
This guide is for SRE, platform and operations leads building a shortlist. It explains what separates these tools, why correlation is not causal evidence, and how to test them against your own past incidents, so you measure what a tool actually finds.
AI root cause analysis vs alert summarization
The first question to ask of any AI root cause analysis tool is: what does it look at before it answers?
Alert summarizers take a single alert, or the messages in an incident channel, and condense them with a language model. The output is readable and useful for handoffs, but the context is limited to the alert text. If the alert says “checkout API error rate high”, the summary describes a checkout API problem, because that is all the model can see.
Telemetry-querying investigation agents chain queries across logs, metrics, traces and recent changes, forming and testing hypotheses as they go. Datadog’s Bits AI SRE, for example, runs investigations over data in Datadog and is billed in AI credits. [4] What these agents can reach is bounded by what they can query during each investigation.
Dependency-aware investigation platforms start from a model of your environment: which hosts, services and data stores exist and which ones call each other. Alerts are grouped and interpreted against that model, and the output is a root cause assessment, an estimate of what is affected, and suggested next steps.
These categories overlap, and one product can combine them. The point is that “automated root cause analysis” on a feature list tells you little until you know which inputs produced the answer.
Correlation vs causal evidence
Most AI RCA starts with correlation: alerts that fire close together, on related hosts, with similar text, get grouped into one incident. That grouping is valuable: dozens of notifications become one thing to investigate. But a correlated group is not a cause.
Three common failure patterns to watch for:
Timing coincidence. Two alerts fire in the same minute because a cron job and a deploy happened to overlap. Similar timing alone does not prove a shared cause.
The loudest symptom. The service with the most alerts is often downstream of the actual problem. A tool that ranks by alert volume will name the victim, not the source.
Healthy neighbors. Services that talk to each other are not necessarily failing for the same reason. Grouping everything behind a load balancer produces one giant, unhelpful incident.
Causal evidence is something you can point to that explains the mechanism: a failing connection between two specific components, a change that landed just before the first symptom, a query plan that scans millions of rows. Some vendors make this explicit. BigPanda’s Root Cause Changes, for example, scores changes as suspects for an incident. [5] Whatever the approach, the tool should show which evidence links the cause to the symptoms, so an engineer can check it.
Why service dependencies matter
Without a dependency model, an AI tool can only guess how two alerts relate, usually from names and timing. With one, it can ask better questions: do these failing services share a database? Which business-facing services sit downstream of the component that broke?
Dependencies matter in three places during AI incident investigation:
Grouping. Alerts on components joined by a failing connection probably belong to the same incident. Alerts on components that merely sit near each other probably do not.
Direction. Dependencies have a direction. If checkout calls payments and payments calls a database, a database fault explains errors in both; a checkout fault does not explain database alarms.
Impact. Following dependency paths outward shows which services may be exposed. A dependency indicates potential exposure, not a confirmed failure, so impact still has to be checked against current signals.
Ask every vendor where its dependency information comes from. A CMDB is only as accurate as its last update. Traces cover only instrumented services. Agent-based discovery sees actual connections but needs installation and permissions. Any discovered map is a snapshot, so ask how often it refreshes.
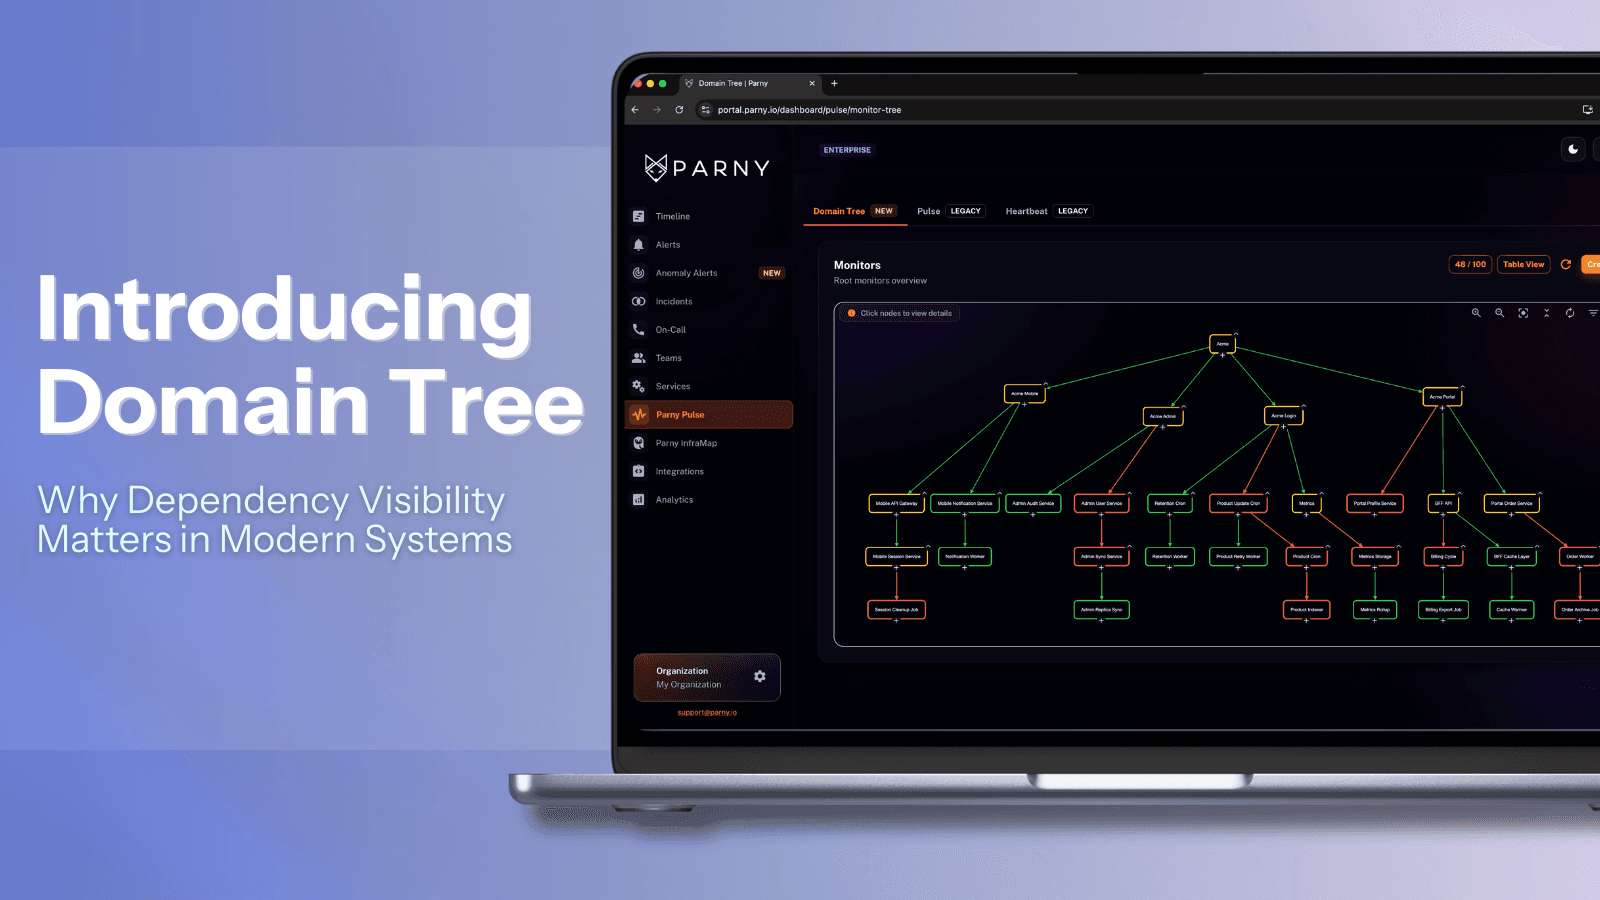
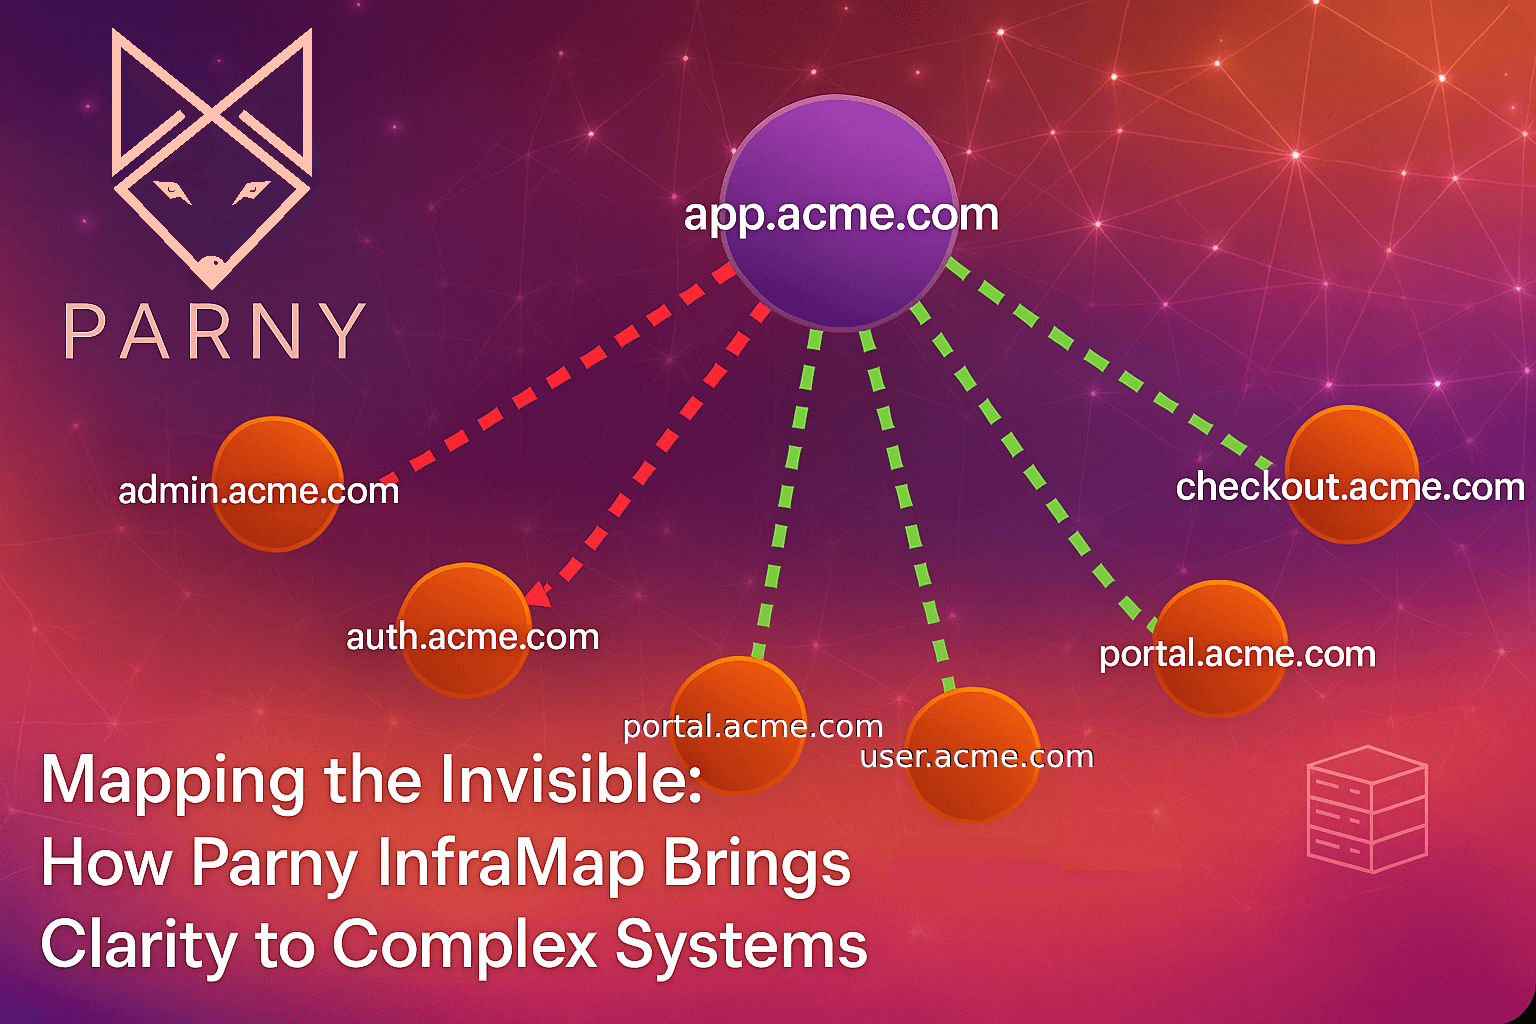
In Parny, service dependencies are discovered by the InfraMap Agent from observed TCP connections, including failing ones, and organized into services and business domains. The same dependency context feeds Parny AI’s incident analysis.
See how Parny connects services, infrastructure and business domains, and how dependency paths show where a failure could propagate.
Root cause assessments vs verified root causes
An AI tool produces a root cause assessment: a hypothesis about what broke and why, built from the evidence it could see. A verified root cause is what your team confirms after checking that hypothesis against logs, metrics, code and changes. Treating an assessment as verified is how teams roll back the wrong deploy or restart the wrong service.
Here is a worked example from Parny’s demo environment.

Demo environment, not customer data. Parny AI groups 13 alerts into one incident and proposes a cause: a merged revenue-report change that added an unindexed orders JOIN. Treat this as a hypothesis to verify, not a confirmed root cause.
In this demo incident, Parny AI groups 13 alerts across 8 hosts into one critical incident, “pg-prod-01 full-table scan overload”. Its assessment reads:
Issue: pg-prod-01 at CPU 97%, IO wait 71% and connections 200/200, from a sequential-scan orders JOIN query.
Cause: “Merged acme-billing revenue-report PR added unindexed orders JOIN query hitting 14M rows.”
Impact: “Checkout API error rate 34.6%, Payments API slow; DB connections rejected.”
It also shows a cascade (a merged change on GitHub, then the saturated database, then checkout-api errors), the affected pools, endpoints and hosts, and an action plan with four steps.
That is a strong hypothesis, and it is still a hypothesis. To verify it, an engineer would check that the change was deployed before the first database alarm, run an execution plan for the new query to confirm the full table scan, compare slow-query logs before and after the deploy, and confirm that checkout errors are database connection failures rather than an unrelated fault. If all four line up, the assessment becomes a verified root cause. If one does not, the team knows exactly which claim failed.
When you evaluate tools, look for outputs that make this verification easy: specific components, a stated mechanism, and evidence you can check in your own systems. Parny’s AI root cause assessment is designed to be reviewed this way, with the cause, potential impact and recommended next steps in one view.
How to test accuracy in a real incident
A vendor demo shows a staged incident with a clean answer. Your evaluation should use incidents where you already know the answer. Here is a procedure to run during a proof of concept.
1. Build an answer key from past incidents. Choose a set of resolved incidents that have a postmortem with a confirmed root cause. Include a bad deploy, a dependency failure, a capacity problem, a third-party outage, and at least one incident where the loudest alert was not the cause. For each, the incident owner writes down the root cause, the first component that failed, and the services actually affected. Keep this key away from the scorers.
2. Recreate the inputs. Replay the original alerts into each tool through the same integrations you use in production, in their original order, or run the tools in shadow mode on live incidents during the trial. Record what context each tool had, and whether any dependency map reflects the environment as it was during the incident.
3. Capture outputs at fixed checkpoints. Save each tool’s assessment, with a timestamp, at its first output and at later checkpoints you define in advance. Tools revise answers as new alerts arrive; you want both the first answer and the trend.
4. Blind-score the assessments. Remove tool names and have two reviewers score each output against the answer key: correct cause and mechanism; right component but wrong mechanism; named a symptom instead of the cause; wrong; or no answer. Record disagreements and why.
5. Measure time to correct hypothesis. For each incident, record the time from the first alert to the first output whose top hypothesis matches the answer key. Compare it with the time your team took to reach the same hypothesis, using your own incident timeline.
6. Check every evidence citation. Can a reviewer trace each claim to a specific alert, metric, dependency or change in your systems? Count claims with no traceable evidence, and any component names that do not exist in your environment.
7. Test the negative cases. Include an unrelated alert that fires during an incident and see whether it stays separate. Include an incident with missing data and see whether the tool says it lacks evidence or guesses anyway.
8. Review the suggested actions. For each recommended step, decide whether it is specific, safe, consistent with your runbooks, and in the right order. Flag any that would have made things worse.
Report results as a scorecard per incident, not one averaged number: a tool that is right on database incidents and wrong on network incidents tells you something an average hides. For a broader buying framework beyond RCA, see our AIOps platform evaluation guide.
Suggested actions vs autonomous remediation
The next line to draw is between a tool that suggests actions and one that takes them. Vendors now describe this boundary explicitly, and it is worth reading their own wording. PagerDuty describes its Paige SRE agent, generally available from 3 November 2026, as giving recommendations with supporting evidence and a confidence level, and acting autonomously only where a team allows it. [1] ServiceNow says of its AIOps AI Specialist, generally available in its November 2026 release: “Remediation requires human approval.” [2] Dynatrace’s SRE Agent investigation template puts it plainly: “A recommended fix isn’t an applied fix.” [3]
Parny AI recommends prioritized next actions; your team reviews them and makes any change through its normal change process. Autonomous remediation is not a released Parny capability.
If a tool does execute actions, ask which ones, under whose credentials, with what approval, and where the audit trail is. Test what happens when the assessment is wrong: an automated action built on a wrong hypothesis is the worst outcome in this category.
Evaluation criteria for enterprise teams
Use this checklist with the test procedure above.
Criterion | What to ask | What to see in the POC |
|---|---|---|
Context source | Does the tool reason over alert text only, queried telemetry, a dependency model, or a combination? | The inputs behind one specific assessment |
Dependency awareness | Where does dependency data come from (CMDB, traces, agent discovery)? | A failing dependency shown for a real incident |
Map freshness | How often is the dependency map updated, and is its age visible? | Last-updated time in the product |
Evidence trail | Can each claim be traced to an alert, metric, dependency or change? | Count of claims with traceable evidence (step 6) |
Symptom vs cause | Does it name the upstream cause or the loudest symptom? | Blind scores from step 4 |
Unrelated alerts | Are coincidental alerts kept out of the incident? | Result of the negative test (step 7) |
Behavior under uncertainty | Does it say when evidence is insufficient? | Output on the missing-data incident |
Impact analysis | How is potential impact estimated, and is it labeled as potential? | Affected services compared with your answer key |
Action boundary | Suggest only, or execute? Approval and audit trail? | Documentation plus a walkthrough |
Existing stack | Which of your monitoring tools does it ingest from? | Your own alerts arriving through your integrations |
Setup footprint | Agents, kernel or cluster permissions, network access? | Install notes for your platforms |
Data handling | What data is sent to the AI model, and what is retained? | Written answers from the vendor |
Pricing model | Per user, per asset, per investigation or per credit? | A cost estimate for your incident volume |
Agent access | Can your own AI agents use the tool’s context (for example through MCP)? | Documentation for the interface |
Where Parny fits in an existing monitoring stack
Parny sits on top of the monitoring and observability tools you already run. It ingests alerts through 40+ integrations, including Datadog, Dynatrace, New Relic, Zabbix, AWS CloudWatch and Sentry. It does not collect application logs, trace requests, or replace APM. Your observability platform stays the source of telemetry; Parny correlates alerts across tools and investigates them in the context of your infrastructure. If Datadog is your main platform, see how Parny works alongside Datadog; the same applies to Parny alongside Dynatrace.
What Parny adds:
Its own infrastructure context. The InfraMap Agent maps TCP connections between hosts and Kubernetes workloads, including failing connections, and Service Discovery groups them into applications and roles. Parny AI uses this map when grouping alerts and estimating impact.
AI incident investigation. Parny AI provides a root cause assessment, impact analysis and prioritized next actions for each incident. Your team verifies the assessment and decides what to do.
Response in the same place. On-call, escalation and incident management run alongside the analysis.
Context for your own agents. Parny AI’s infrastructure context is available to your AI agents through MCP. Agent-to-agent (A2A) collaboration is coming soon.
Where it fits less well: Parny is not a full APM or log management product. If you cannot install an agent, Parny AI still works on alerts from your integrations, but with less context: dependency-aware grouping and failing-connection evidence require the InfraMap Agent. And if your evaluation requires a tool that remediates incidents on its own, Parny does not do that today. Teams with ITSM-centered processes can see Parny and ServiceNow compared.
Follow an incident from related alerts through dependency context to a root cause assessment, potential impact and recommended next steps.
Sources
[1] SiliconANGLE: PagerDuty debuts Paige AI agent with renamed PD Reliability Platform and PD Labs (3 Nov 2026)
[2] ServiceNow Community: Shift Left of Traditional IT Operations with the AIOps AI Specialist (November 2026 release)
[3] Dynatrace: Release Radar 10.26 (5 Nov 2026)
[4] Datadog: Pricing, including Bits AI credits (accessed 10 Nov 2026)
[5] BigPanda documentation: Root Cause Changes (accessed 10 Nov 2026)
Frequently asked questions
What are AI root cause analysis tools?
AI root cause analysis tools use machine learning and language models to propose why an incident happened. They differ in what they examine: some summarize alert text, some query logs, metrics and traces, and some reason over a model of service dependencies. The output is a root cause assessment that engineers should verify.
Can AI root cause analysis be trusted?
Treat it as a hypothesis, not a verdict. A useful assessment names specific components, states a mechanism and points to evidence you can check in your own systems. Test accuracy before relying on it by replaying past incidents with known root causes and blind-scoring the results.
Does AI root cause analysis replace monitoring tools?
No. AI RCA tools depend on monitoring and observability data. Parny, for example, ingests alerts from tools such as Datadog, Dynatrace and Zabbix and adds infrastructure dependency context; it does not collect application logs, traces or replace APM.
What is the difference between correlation and root cause?
Correlation groups alerts that appear related, by timing, host or text. A root cause explains the mechanism that produced them, such as a failing dependency or a recent change. Correlated alerts can share a cause, but similar timing alone does not prove one.
Do AI RCA tools fix incidents automatically?
Some vendors offer automated actions with approval controls; many recommend actions for humans to carry out. Parny AI recommends prioritized next actions, and your team reviews them and makes changes through its normal change process. Autonomous remediation is not a released Parny capability.
How do you evaluate an AI root cause analysis tool in a POC?
Replay past incidents that have confirmed root causes, capture each tool’s output at fixed checkpoints, and have reviewers blind-score them against the known answer. Measure time to the correct hypothesis, check that every claim cites traceable evidence, and include negative cases such as unrelated alerts.